Vibe coding is cheap to start and expensive to finish. Amazon’s Kiro wants the spec written first.
OpenAI moved Codex to token-based credits in April, GitHub Copilot followed in June, and Cursor ended its flat-rate pricing in August, a month after launching an India-only plan at Rs 649. Because each attempt drags along everything the agent read before it, every one of those loops is billed, and they do not add up in a straight line,. The tool is Kiro, the development environment Amazon launched a year ago, designed around the opposite instinct: settle a written specification first, argue it out line by line, and generate nothing until the document is agreed.
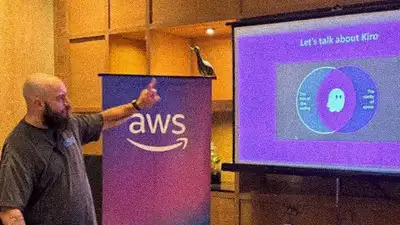
Amazon calls this spec-driven development, and Mesaros says the time it takes upfront is why he rarely has to redo work. “When I build something with spec-driven development, I can usually one-shot things,” he said. It writes the code, runs the tests, reads the error it just caused and tries again. There is a name for working this way, vibe coding, where the developer describes what they want in rough terms and lets the model fill in the rest. Developers now spend more of the day watching that than typing. Ten tries cost more than ten times one try. A flat monthly fee used to absorb that. This year nearly every major coding tool switched to charging for what gets used, and the sums became the developer’s problem. Darko Mesaros has spent much of the past year arguing developers off that habit. A distinguished developer advocate at AWS, he spends his week in front of developers, explaining how the company’s tools work and building with them himself. “Even though it’s a bigger lift initially, it can literally one-shot things instead of iterating over multiple loops and costing many tokens. The billing shift behind that argument happened fast. Claude Code now runs a weekly cap over a rolling five-hour limit.
Hand a coding task to an AI agent today and it keeps going on its own.
Running a task on Sonnet 4.6 instead costs about 1.3 times as many of Kiro’s credits for the same work. AWS says the homegrown trading platform Dhan built a real-time charting system supporting more than 170 indicators in eight weeks with one engineer, against an estimate of 12 to 24 months. Because it felt like a slow way to work, and the billing is why Mesaros thinks it is coming back, developers let the specification go.
“When I’m certain on the spec and we go through all the things and I agree on all the things modified, it takes that spec,” he said. “If the task is super simple, it’s probably going to use the smaller model, which is a lot faster,” Mesaros said. Start with the attempts. A Kiro spec is three files the tool drafts and the developer approves before any code exists. The requirements file lists user stories in EARS notation, a format from safety-critical engineering where every line is a condition and a response: when a user submits a form with invalid data, the system shall show errors next to the relevant fields. The design file sets out the architecture, and the tasks file breaks the build into steps that run in parallel. Mesaros puts the weight on the approval, not the drafting. Changing direction while the requirements are open costs an edited line, where the same change after generation means another full pass over the codebase. Model choice goes to a router Kiro calls the auto model, which sits in front of a catalogue spanning Anthropic, OpenAI and open-weight models, reads the prompt and decides what should handle it. “But if it’s something more complex, it’s going to choose accordingly. He is careful to say the router works on complexity, with the cost following close behind. The router also picks once, at the start of a task, and stays with it, which keeps the cache intact. Context is loaded the same way. Memory and lessons come in once, when a session opens, and each turn after refreshes only the project rules and short references to relevant skills. Mesaros points to the semantic memory underneath, a vector database the agent queries instead of reloading instruction files wholesale, which he calls the more optimised route. Glimmertech, another customer, credits the structure with catching what it calls Potemkin house problems, where code looks finished but does not work underneath. Both accounts come from Amazon and are unverified. Nor does Amazon claim any of it comes free. Its own guide calls this an engineering investment and warns the first few weeks feel slower. Everyone else is arriving at some version of the idea anyway, since Claude Code reads a CLAUDE.md file into every request, Codex reads AGENTS.md and Cursor supports rules files. None of it is new either. EARS came out of aircraft and medical devices, where finding out later was never an option. What has changed is who the document is for. For decades it was written for whichever engineer inherited the project two years on, and it was the first thing dropped when a deadline arrived. Now a machine reads it at the start of every session, and every reading turns up on the bill. You use AI every day. Now get your AI Quotient. Take the AIQ test.
Writing the requirements before the code is what software engineering did for decades, until it came to look like an expensive way to be slow.
The same capability costs less every few months, and Anthropic has held Sonnet 5 at two dollars per million input tokens after dropping a planned increase in August. The price per token is not the reason. What grew is the work behind a single instruction, since an agent that opens a repository, writes a file, runs the tests and tries again spends tokens on every cycle, and the context it carries grows as it goes. Providers have a partial fix, called prompt caching. A model stores the unchanged opening portion of a request and reads it back later at a tenth of the normal input price. It only works if that portion is identical, character for character, so a timestamp near the top of a prompt or a model swapped mid-task will break it. Nothing flags that, and teams find out from the invoice. So one team can pay ten times what another pays for identical work. Three things decide it: which model picks up the job, how many attempts it takes, and how much of the context can be read from cache. Kiro goes after all three.